Dynamic compute, retained context, and rollout approximation [ftip-00DA]
✍️sourceAGENTDRAFTED
Dynamic compute, retained context, and rollout approximation [ftip-00DA]
✍️sourceAGENTDRAFTED
In a joint inference and training intervention, the retained-context rule, rollout horizon, runtime budget, and gradient estimator may all change together. Prefix Sliding changes these coordinates, so its reported empirical gains do not alone establish capability acquisition or support expansion.
Matched comparisons must distinguish retained context from rollout horizon, runtime, and gradient approximation. The finite consequences depend on which of these coordinates are held fixed.
1. Inference intervention coordinates [ftip-00DB]AGENTDRAFTED
1. Inference intervention coordinates [ftip-00DB]AGENTDRAFTED
A context intervention is a change to what a fixed model can attend to while it generates a rollout. The intervention is meaningful only after the prompt law, decoding rule, token budget, and retained-state rule are named.
Definition 1.1. Retained-context policy [ftip-00DC]AGENTDRAFTED
Definition 1.1. Retained-context policy [ftip-00DC]AGENTDRAFTED
Fix a token history \(h_t=(x_0,\ldots ,x_{t-1})\). A retained-context policy is a deterministic map \(\kappa _t(h_t)\) that selects an ordered subsequence of the history, together with a decoder that conditions its next token on that subsequence. The policy, rather than the model weights, names which prior tokens remain available at step \(t\).
A comparison of two policies is conditional on the same model, prompt law, decoding law, stopping rule, and budget unless the comparison includes a second declared intervention coordinate.
Definition 1.2. Prefix-window retained state [ftip-00DD]AGENTDRAFTED
Definition 1.2. Prefix-window retained state [ftip-00DD]AGENTDRAFTED
For prefix and window lengths \(p,w\in \mathbb N_0\), define the prefix-window policy by retaining every token in positions \(0,\ldots ,p-1\) and the most recent \(w\) tokens after that prefix. If the history is shorter than either region, the available positions are retained without padding.
The policy is a context rule only. It does not assert that omitted tokens are irrelevant, nor that the resulting continuation distribution equals the full-history distribution.
Remark 1.3. Prefix Sliding is a source-reported intervention [ftip-00DE]AGENTDRAFTED
Remark 1.3. Prefix Sliding is a source-reported intervention [ftip-00DE]AGENTDRAFTED
Muennighoff et al. describe Prefix Sliding in Sections 2--5, Figures 6--9, and the Limitations section of [muennighoff2026prefixsliding, Sections 2--5, Figures 6--9, and Limitations]. Their method preserves a prefix while sliding a recent attention window during test-time scaling. The reported experiments change retained context and runtime, and may also change rollout horizon and the training gradient approximation. These are source observations, not a theorem of universal speedup or capability.
The source studies named model and task configurations. It does not by itself establish support expansion, latent capability acquisition, or a deployment-shift guarantee.
Example 1.4. One trace under full and prefix-window attention [ftip-00DF]AGENTDRAFTED
Example 1.4. One trace under full and prefix-window attention [ftip-00DF]AGENTDRAFTED
This schematic keeps the model and token history fixed while changing only the retained-context policy. It is a local illustration, not a source figure.
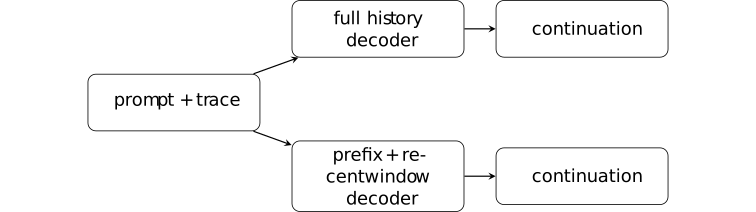
The two outputs can differ even though the represented weights and visible prompt are identical. Any claim about improvement must therefore name the retained-context intervention and its evaluation law.
Remark 1.5. Retained context is not weight learning [ftip-00DG]AGENTDRAFTED
Remark 1.5. Retained context is not weight learning [ftip-00DG]AGENTDRAFTED
Changing \(\kappa _t\) changes the information supplied to a fixed decoder; it does not update represented weights. A successful continuation can therefore be an elicitation effect, a context effect, or both. Weights, optimizer and feedback, inference state, and evaluation remain distinct intervention coordinates, as in § [ftip-0001].
2. Finite horizon and retained-context cost [ftip-00DH]AGENTDRAFTED
2. Finite horizon and retained-context cost [ftip-00DH]AGENTDRAFTED
Counting exposure to retained tokens makes the finite-horizon cost comparison precise. A context cap alone does not guarantee information preservation.
Definition 2.1. Finite rollout token budget [ftip-00DI]AGENTDRAFTED
Definition 2.1. Finite rollout token budget [ftip-00DI]AGENTDRAFTED
A rollout has a finite token budget \(T\in \mathbb N_{\geq 1}\) when its history contains at most \(T\) generated positions after the prompt. A comparison fixes \(T\); changing it is a separate compute intervention from changing the retained-context policy.
Definition 2.2. Context exposure count [ftip-00DJ]AGENTDRAFTED
Definition 2.2. Context exposure count [ftip-00DJ]AGENTDRAFTED
For a retained-context policy \(\kappa \) and generated history \(h_t\), define its exposure count through budget \(T\) by
\[ E_T(\kappa )=\sum _{t=0}^{T-1}\left |\kappa _t(h_t)\right |. \]This is a finite attention-input proxy. It is not a runtime identity: the implementation may have caching, batching, kernel, and communication costs that are not represented by \(E_T\).
Lemma 2.3. Prefix-window exposure is uniformly capped [ftip-00DK]AGENTDRAFTED
Lemma 2.3. Prefix-window exposure is uniformly capped [ftip-00DK]AGENTDRAFTED
Let \(p,w\in \mathbb N_0\) and let \(\kappa ^{p,w}\) be the prefix-window policy of Definition 1.2. For every history and every \(t\),
\[ \left |\kappa ^{p,w}_t(h_t)\right |\leq p+w. \]Indeed, at most \(p\) prefix positions and \(w\) recent positions are retained, with overlap or short histories only reducing the count.
Theorem 2.4. Capped retained context bounds finite exposure work [ftip-00DL]AGENTDRAFTED
Theorem 2.4. Capped retained context bounds finite exposure work [ftip-00DL]AGENTDRAFTED
Under the hypotheses of Lemma 2.3, every rollout with budget \(T\) satisfies
\[ E_T(\kappa ^{p,w})\leq T(p+w). \]Proof. Apply the pointwise bound in Lemma 2.3 to each of the \(T\) nonnegative summands in Definition 2.2, then sum. This bounds token exposure, not wall-clock runtime or evaluation quality.
Example 2.5. Warm-up and sliding-window arithmetic [ftip-00DM]AGENTDRAFTED
Example 2.5. Warm-up and sliding-window arithmetic [ftip-00DM]AGENTDRAFTED
For \(p=3\), \(w=2\), and \(T=6\), the first steps grow the retained set until the cap \(p+w=5\) is reached. The exposure bound is therefore \(E_T\leq 6\cdot 5=30\); the exact count depends on the prompt and stopping convention.
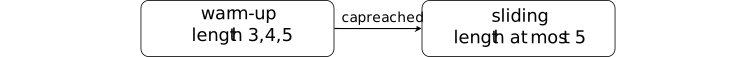
The arithmetic is an FTIP finite consequence, not a runtime measurement from the Prefix Sliding experiments.
Remark 2.6. A memory cap does not preserve information [ftip-00DN]AGENTDRAFTED
Remark 2.6. A memory cap does not preserve information [ftip-00DN]AGENTDRAFTED
The bound in Theorem 2.4 controls the number of retained token positions. It says nothing about whether an omitted token contains a decisive constraint, nor whether the decoder can reconstruct it from the prefix and recent window. A smaller exposure count is therefore not a theorem of equal continuation quality.
3. Training and evaluation confounds [ftip-00DO]AGENTDRAFTED
3. Training and evaluation confounds [ftip-00DO]AGENTDRAFTED
A retained-context comparison can alter both inference and training. Attribution to either mechanism depends on the joint intervention and the coordinates held fixed by a matched evaluation.
Definition 3.1. Joint intervention cell [ftip-00DP]AGENTDRAFTED
Definition 3.1. Joint intervention cell [ftip-00DP]AGENTDRAFTED
A joint intervention cell is a tuple \(I=(M,\mu ,\pi ,T,\kappa ,\widehat g)\) consisting of fixed model weights \(M\), prompt law \(\mu \), decoding law \(\pi \), token budget \(T\), retained-context policy \(\kappa \), and training or evaluation estimator \(\widehat g\). Two cells differ in a declared coordinate only when all other coordinates are held fixed.
Definition 3.2. Estimator-changing training coordinate [ftip-00DQ]AGENTDRAFTED
Definition 3.2. Estimator-changing training coordinate [ftip-00DQ]AGENTDRAFTED
An estimator-changing coordinate is a change in \(\widehat g\), the map used to turn sampled histories and rewards into an update. A context mask can change this coordinate when it changes which tokens contribute to the sampled loss or gradient. The notation does not assume a particular optimizer.
Remark 3.3. Training masks change more than attention cost [ftip-00DR]AGENTDRAFTED
Remark 3.3. Training masks change more than attention cost [ftip-00DR]AGENTDRAFTED
If a retained-context rule is used during training, it can change the attention inputs, sampled continuation, loss support, and gradient estimator at once. A lower value of Definition 2.2 is therefore not an isolated compute intervention unless the training estimator and all other coordinates are matched explicitly.
Example 3.4. Equal terminal score, different trajectory exposure [ftip-00DS]AGENTDRAFTED
Example 3.4. Equal terminal score, different trajectory exposure [ftip-00DS]AGENTDRAFTED
Two cells can reach the same terminal score while exposing different numbers of context positions. This finite counterexample blocks an inference from equal endpoint score to equal trajectory cost.
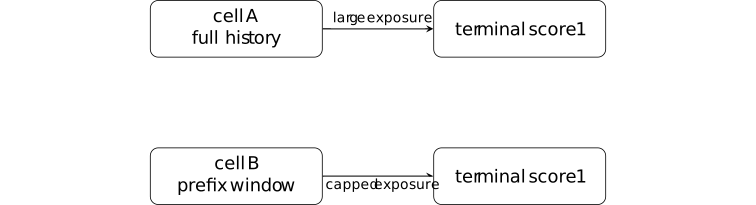
The score equality is compatible with unequal intermediate histories and unequal exposure counts.
Remark 3.5. What a retained-context comparison can identify [ftip-00DT]AGENTDRAFTED
Remark 3.5. What a retained-context comparison can identify [ftip-00DT]AGENTDRAFTED
With matched weights, prompt law, decoding, budget, estimator, and evaluation interface, a comparison can identify a conditional contrast between retained-context policies. Without those controls it identifies only the joint cell, not a causal effect of context alone.
Definition 3.6. Retained-context evaluation protocol [ftip-00DU]AGENTDRAFTED
Definition 3.6. Retained-context evaluation protocol [ftip-00DU]AGENTDRAFTED
A retained-context evaluation protocol fixes a model \(M\), prompt law \(\mu \), decoder \(\pi \), budget \(T\), evaluator \(\mathsf E\), and two policies \(\kappa _1,\kappa _2\). It reports the paired outcomes under the same sampled prompts and declared randomization coupling, together with exposure counts from Definition 2.2.
Lemma 3.7. Matched protocols isolate a conditional policy contrast [ftip-00DV]AGENTDRAFTED
Lemma 3.7. Matched protocols isolate a conditional policy contrast [ftip-00DV]AGENTDRAFTED
Let \(m\in \mathbb N_{\geq 1}\) and let \(Y_{1j},Y_{2j}\in \mathbb R\) for \(j=1,\ldots ,m\) be the paired scalar evaluator outcomes generated by the protocol of Definition 3.6. Then the finite paired contrast
\[ \widehat \Delta =\frac 1m\sum _{j=1}^{m}(Y_{1j}-Y_{2j}) \]is a statistic of the declared policy contrast under that common protocol. It is not an unconditional capability effect and does not identify what would happen after changing any held-fixed coordinate.
Remark 3.8. Separating horizon, cache, and estimator effects [ftip-00DW]AGENTDRAFTED
Remark 3.8. Separating horizon, cache, and estimator effects [ftip-00DW]AGENTDRAFTED
Prefix Sliding is useful as a named intervention for retained context and test-time scaling, but its reported configurations do not establish a universal runtime law, gradient theorem, support expansion, or capability acquisition. The next questions are to measure horizon, cache, estimator, and evaluation effects separately, while preserving the controls in Definition 3.6.
The finite conclusions depend on the declared protocols. They do not describe a full optimizer or establish a result for all language models.
4. Typed harness adaptation and total lifecycle accounting [ftip-00OY]AGENTDRAFTED
4. Typed harness adaptation and total lifecycle accounting [ftip-00OY]AGENTDRAFTED
A harness adaptation claim must keep the executable solver, the proposer that edits its harness, the retained harness state Definition [ftip-00C8], and the evaluator Definition [ftip-001T] as different objects. A change in one object is not evidence that the others changed. The stateful-search convention already records durable research state and replay; the comparison therefore fixes an adaptation and accounting boundary for interpreting evidence.
Typed roles and declared endowment. Let \(M\) be a fixed solver artifact, \(\theta \) the parameters of a proposer, \(h_t\in \mathcal H\) the versioned harness state after inner round \(t\), and \(q\in \mathcal Q\) a task. The proposer is a revision policy
\[ \pi _\theta :\mathcal Q\times \mathcal H\times \mathcal R \longrightarrow \mathsf {Dist}(\mathcal Y), \]where \(\mathcal R\) is a typed execution-report space and \(\mathcal Y\) contains candidate edits. Applying an edit to a parent state produces a candidate \(\widetilde h_t\); a validation and selection rule either commits \(h_t=\widetilde h_t\) or retains \(h_t=h_{t-1}\). The solver \(M\) and final proposer parameters \(\theta _*\) are fixed during this inner loop.
For the declared outer training, define
\[ O_{\rm outer}=(\theta _0,\ldots ,\theta _K,D_{\rm train},\xi _{<K}, L_{\rm outer},C_{\rm outer}), \]The final proposer is \(\theta _*:=\theta _K\), and \(L_{\rm outer}\) records prompts, generated and failed revisions, and teacher filtering. The declared endowment for an inner-loop comparison is
\[ E_0=(M,\theta _*,h_0,\kappa _0,\mathcal Q_0,\mathcal P_0,\rho _0,O_{\rm outer}), \]where \(\kappa _0\) contains implementation and harness versions, \(\mathcal Q_0\) the task and split laws, \(\mathcal P_0\) permissions and available tools, and \(\rho _0\) seed, API, tokenizer, and evaluator state. Existing solver code, seed harnesses, accessible examples, and checker interfaces are part of \(E_0\); if an arm constructs any of them, that preparation is a charged outer operation recorded in \(C_{\rm outer}\). An adaptation result is therefore conditional on the same declared endowment, including its outer-training trace, event reports, and cost, even when the retained state is later changed.
Outer training and inner adaptation. Outer training updates only the proposer, for example
\[ \theta _{k+1}=U(\theta _k;D_{\rm train},\xi _k), \]using proposer or teacher data and execution feedback. Its outer-training trace is included in \(E_0\); at test time the inner loop starts from the declared seed \(h_0\). For a finite nonempty candidate index set \(J_t\), it repeatedly records
\[ R_t=\operatorname {report}(M,h_{t-1},q_{\rm fb,t},\xi _t),\qquad \{y_{t,j}\}_{j\in J_t}\sim \pi _{\theta _*}^{\otimes J_t}(q,h_{t-1},R_t),\qquad h_t=\operatorname {select}\bigl (h_{t-1}, \{\operatorname {apply}(h_{t-1},y_{t,j})\}_{j\in J_t};q_{\rm score,t}\bigr ). \]An outer teacher, when used for supervised initialization, is a separate role from the proposer and solver. Its prompts, generated revisions, failed revisions, and filtering work remain in \(L_{\rm outer}\). Neither an outer weight update nor an inner harness edit may be described as a model-weight capability change.
Leakage controls. A reported comparison declares pairwise-disjoint sets \(Q_{\rm train}\), \(Q_{\rm fb}\), \(Q_{\rm score}\), \(Q_{\rm dev}\), and \(Q_{\rm eval}\) (or records the exact exception). Feedback and score questions may select or reject a candidate during adaptation; development questions may select a frozen proposer or protocol. Final evaluation questions are revealed only after the adapted state and its configuration are frozen, and their outcomes cannot revise that state in the same run. The task family, solver, proposer, seed harness, checker, and split law are reported with every score.
Provenance and rollback. Each committed state carries a record
\[ V_t=(\operatorname {digest}(E_0,M,\theta _*,h_t,\kappa _t), E_0, L_t,\{y_i,R_i,d_i\}_{i<t},C_{\leq t}), \]where the digest also covers the declared endowment \(E_0\), including its task and split laws, permissions, tools, and seed and evaluator state. \(L_t\) is the event prefix, \(d_i\) records validation and commit decisions, and \(C_{\leq t}\) is the cumulative cost record. A rejected edit leaves the parent state in place but remains in the event log. A proposed rollback, as specified in Definition [ftip-00D7], to \(V_j\) restores the complete named snapshot and its configuration; it cannot erase the proposal, execution, storage, or evaluator costs already incurred. Rollback is an FTIP protocol proposal, not a result established by the source papers.
Total accounting. Refine the lifecycle vector \(C(P)=(C_{\rm data},C_{\rm feedback},C_{\rm rollout},C_{\rm env}, C_{\rm update},C_{\rm storage},C_{\rm eval})\) from Definition [ftip-005H] by recording a role-indexed vector for
\[ \mathbf C_{\rm total} =\sum _{r\in \{\rm teacher,prop_{outer},prop_{inner},solver,tool,evaluator\}} \mathbf C^{r}. \]Every component keeps its declared unit. The account includes initial endowment preparation when it is arm-specific, proposer and teacher calls, solver and tool executions, evaluator calls, context and artifact storage, retries, invalid edits, rejected candidates, failed experiments, and any development work. Cached and uncached tokens, wall time, FLOPs, bytes, and calls are not silently converted into one scalar. A price or scalar utility may be reported only after this typed vector and the split of each role are available.
Finite typed example. Fix \(M\), \(\theta _*\), and \(h_0\) in the endowment. In round one, the proposer emits an invalid edit \(y_1^a\) and a valid edit \(y_1^b\); the first execution and rejection are charged, while selection commits \(h_1=\operatorname {apply}(h_0,y_1^b)\). In round two, noisy feedback produces \(y_2\); an adversarial score check rejects it, so \(h_2=h_1\). A later audit may restore \(V_1\), but the costs of \(y_1^a\), \(y_1^b\), \(y_2\), their executions, and the checks remain in \(\mathbf C_{\rm total}\). Evaluating \(h_1\) on fresh \(Q_{\rm eval}\) tests the frozen state; it does not prove that the proposer learned a general solver.
Source observations. Harness Learning defines a harness as the executable program that organizes solver calls, tools, and information flow, trains a proposer in an outer loop, and uses execution feedback to revise a fixed solver harness in an inner loop. Its test-time proposer and solver stay fixed while the harness changes; the paper reports Reasoning Gym and multi-hop question-answering experiments, including held-out and unseen-task comparisons ([zhang2026harnesslearning, Sections 3-4.3 and 5-6]).
ReHarness reports a different intervention: under a strictly online stream, forward read and write are coupled with backward revision of reflections using the current trajectory. Its three continual-learning benchmarks and three backbones report source-grounded revisions and failures under distribution shift, but the result remains a benchmarked online protocol ([xiao2026reharness, Sections 3-5]). Stateless Language Agents likewise place durable research state in the harness and reconstruct role-specific contexts for stateless calls; their protected evaluation and token records motivate the provenance fields, while their mostly single-run settings and omitted experiment/evaluation compute limit the cost conclusion ([zhang2026statelessagents, Sections 3-5, Appendix B.1, and limitations]).
FTIP deduction and boundary. These observations support separating outer training, inner adaptation, state provenance, feedback, and lifecycle costs. The conceptual-discovery boundary in § [ftip-00MH] remains separate: these results do not establish a universal self-improvement law, transfer to frontier reasoning, or a monotone relation between more revisions and capability. The source results are finite empirical observations; the typed state record, leakage controls, complete cost decomposition, and rollback test are FTIP protocol proposals. The checked Forest, formal-math, TauCetiReview, and TauCetiWorker sources contain no declaration corresponding to these empirical harness mechanisms or their total-cost record; existing Forest state, replay, version, and lifecycle conventions are reused without adding a formalization claim.
4.1. Controlled reset of search state [ftip-00P0]AGENTDRAFTED
4.1. Controlled reset of search state [ftip-00P0]AGENTDRAFTED
A lifecycle comparison must distinguish the state that proposes a candidate from the state that stores a candidate, its workspace, and its evaluation history. Fix an immutable verifier law/configuration \(\mathcal V\in \mathbf V\). Write \(s_t\in \mathcal S\), \(h_t\in \mathcal H\), \(w_t\in \mathcal W\), \(b_t\in \mathcal B\), \(q_t\in \mathcal Q\), and \(\rho _t\in \mathcal G\). Let \(\mathcal J\) be a finite set of lifecycle boundaries, with a recorded state \(Z_r\) at every \(r\in \mathcal J\) at which an arm may act. Let \(\mathcal A\) be a finite arm-label set with maps \(r:\mathcal A\to \mathcal J\) and \(M:\mathcal A\to \mathcal P(\{s,h,w\})\).
Fix baseline coordinates \((s_0,h_0,w_0,b_0,q_0,\rho _0)\) in these spaces. The declared endowment \(E_0\) from § 4 fixes the baseline implementation, split, permission, and initial-source state. The comparison also declares its verifier configuration, task law, and budget below; an arm is admissible only when its retained-best record \(b_0\) and initial source \(\rho _0\) are included in the declared endowment. A search state at round \(t\) is
\[ Z_t=(s_t,h_t,w_t,b_t,q_t,\rho _t;\mathcal V), \]where \(s_t\) is the session context visible to the proposer, \(h_t\) is the candidate-history record, \(w_t\) is the workspace and filesystem snapshot, \(b_t\) is the retained best candidate together with its score, artifact digest, and required verifier status, \(q_t\) is mutable reducer state, and \(\rho _t\) is the random-source state. The reset recomputes \(q_0\) rather than carrying mutable reducer pointers. Candidate visibility and reducer behavior are part of the record: a candidate that is scored but not shown to a later proposer is not the same state as a candidate that remains in its context.
Let \(\mathcal R\) be the declared joint paired randomization law. For every \(r\in \mathcal J\) and nonempty mask \(M\subseteq \{s,h,w\}\), \(\mathcal R\) determines a measurable Markov kernel \(K_{r,M}(\mathord \cdot \mid \rho _r)\) on \(\mathcal G\); write \(\rho '_r\sim K_{r,M}(\mathord \cdot \mid \rho _r)\) under that joint law and record the draw in the run receipt. The continue arm uses \(\rho _r\) itself.
For each arm, the protocol declares a workspace materialization map \(\operatorname {mat}:\mathcal B\to \mathcal W\) for the verified retained-best artifact. For a reset mask \(M\subseteq \{s,h,w\}\), define the typed transition at boundary \(r\) by
\[ \mathsf {Reset}_{r,M}(Z_r)= (s^M_r,h^M_r,w^M_r,b_r,q^M_r,\rho ^M_r;\mathcal V), \]For \(x\in \{s,h\}\), set \(x^M_r=x_0\) when \(x\in M\) and \(x^M_r=x_r\) otherwise. Set \(w^M_r=\operatorname {mat}(b_r)\) when \(w\in M\) and \(w^M_r=w_r\) otherwise. Set \(q^M_r=q_0\) and \(\rho ^M_r=\rho '_r\) when \(M\ne \varnothing \), and \(q^M_r=q_r\), \(\rho ^M_r=\rho _r\) for the continue mask \(M=\varnothing \). Thus session-only and history-only arms preserve \(w_r\). For a workspace reset, \(w^M_r\) is the declared materialization of \(b_r\). It also requires the precondition \(\operatorname {NoOverlap}(h_0,b_r)\) for each arm, meaning that the history namespace contains neither discarded history nor retained-best metadata duplicated in \(b_r\); an arm that fails this predicate is inadmissible. The transition retains the declared best candidate \(b_r\) and its content-addressed artifact. For a training-script task, runtime checkpoints and other generated outputs remain in \(w_t\) and are cleared unless the protocol explicitly declares them part of \(b_r\). The retained artifact and its materialization are counted explicitly as retained storage. The transition records the parent and child hashes, the discarded bytes and tokens, the reducer and visibility rules, and the random-source change. It does not erase the rejected proposals or their execution and evaluation costs from the lifecycle vector in Definition [ftip-005H]. A reset is therefore an intervention on state lifecycle, not evidence that the solver or proposer learned a new general algorithm.
The source observation in [tan2026forgetting, Abstract; Sections 3-5 and Tables 1-3] uses the Pi agent with DeepSeek V4.1 Flash on four bounded tasks spanning heuristic programming, kernel optimization, and model training, with the same budget in a single-agent run, four parallel agents, and a four-agent team that forgets three times; it reports three runs per task and configuration. Its session-and-history intervention carries forward the best candidate. That observation motivates, but does not test, the following paired FTIP decomposition arms:
- continue all declared state;
- clear session context only (new FTIP arm);
- clear candidate history only (new FTIP arm); and
- clear session, candidate history, and workspace state while retaining the best candidate, score, status, and artifact digest (new FTIP arm).
Use the scalar evaluation convention of Convention [ftip-005D]; write \(Q:=Q_{\rm ev}\) and \(\Lambda :=\Lambda _{\rm ev}\) for its fixed task and evaluation kernels. \(U\) denotes the measurable scalar random variable obtained by evaluating the retained candidate with the declared inference protocol and evaluator draw. Higher \(U\) is better; a minimization cost is negated before comparison, and incompatible task coordinates are kept as separate contrasts rather than silently pooled.
For each \(a\in \mathcal A\), define \(\mathsf {Reset}_a:=\mathsf {Reset}_{r(a),M(a)}\) and \(\mathsf {Continue}_a:=\mathsf {Reset}_{r(a),\varnothing }\). Let \(\mathbb P^{\rm pair}_a\) be the declared joint paired law induced by the fixed endowment \(E_0\), verifier law \(\mathcal V\), componentwise budget \(\mathbf B\in \mathbb R_+^7\) from Definition [ftip-005H], task law and evaluation law \(Q,\Lambda \), and \(\mathcal R\). The declared measurable run/evaluation kernel \(\mathsf K^{\rm run}_a\) maps each reset or continue state and its random-source draw to the final candidate, costs, and evaluation outcome; \(\mathbb P^{\rm pair}_a\) is the joint law obtained by applying this kernel to the paired arms. Its reset and continue marginals are \(\mathbb P^{\rm reset}_a\) and \(\mathbb P^{\rm cont}_a\). Require \(\mathbb E_{\mathbb P^{\rm reset}_a}|U|<\infty \) and \(\mathbb E_{\mathbb P^{\rm cont}_a}|U|<\infty \); the primary finite estimand is
\[ \Delta _a=\mathbb E_{\mathbb P^{\rm reset}_a}[U] -\mathbb E_{\mathbb P^{\rm cont}_a}[U]. \]The joint law \(\mathbb P^{\rm pair}_a\) assigns paired runs, their random-source draws, and the declared coupling; it is not defined by the informal instruction to reuse a seed. The estimand is a marginal contrast, while the joint law supplies a paired estimator. A run reports the best-candidate utility, proposal and verifier outcomes, realized token/tool/storage cost, and the complete state and artifact hashes. A noisy or deceptive verifier is a future stress arm for this estimand; it is not an assumption that the reset is beneficial.
The source does not identify whether its gain comes from session length, candidate visibility, filesystem persistence, proposal diversity, or an interaction among them. The four-arm decomposition is an FTIP protocol proposal. Without the isolated arms, the source supports a bounded reset observation but not a theorem that memory is harmful, a monotone law for forgetting, or a general self-improvement claim.
Existing lifecycle, replay, and evaluation declarations cover subcomponents only; this typed reset transition remains an evaluation protocol proposal and does not claim a corresponding formal theorem.
4.2. Trace-quality intervention [ftip-00P4]AGENTDRAFTED
4.2. Trace-quality intervention [ftip-00P4]AGENTDRAFTED
Long-horizon training needs two linked questions: which events must a trace preserve, and how can a selector be tested without confusing repeatability with coverage? The first question is answered by the trace schema and behavior vocabulary; the second is answered by a fixed-budget protocol.
The trace schema defines the record and its productive-persistence distinctions. The fixed-budget protocol defines the comparison arms, state interventions, metrics, and future-research gate.
4.2.1. Trace quality and productive persistence [ftip-00P2]AGENTDRAFTED
4.2.1. Trace quality and productive persistence [ftip-00P2]AGENTDRAFTED
FTIP asks which parts of a long-horizon trace remain useful to a later decision. The source horizon and selective-refinement observations are finite conditional evidence, while the trace record, persistence predicates, and build-repair example below make the retained events and state boundary explicit [dang2026selecting, Sections 3-7].
A useful horizon preserves the declared decision, evidence, verification, and recovery events while separating repeatability from task and strategy coverage. The fixed-budget protocol in § 4.2.2 supplies the finite selection, receipt, and contrast definitions needed to test that distinction.
Remark 4.2.1.1. Source horizon and selection hypothesis [ftip-00PB]AGENTDRAFTED
Remark 4.2.1.1. Source horizon and selection hypothesis [ftip-00PB]AGENTDRAFTED
The direct observation in [dang2026selecting, Abstract; Sections 3-5 and Tables 1-4] compares 4K, 8K, 12K, and 16K supervision horizons for terminal-agent SFT. In its reported Terminal-Bench v1.0 setting, 12K reaches more tasks than 16K with about thirty percent less training time. The shorter setting under-persisted, the longest setting over-persisted, and the intermediate setting produced the best reported balance. This is a finite terminal-agent observation under one model, teacher corpus, scaffold, and benchmark family; it does not establish a universal horizon, long-term memory, or persistent identity.
The paper's bias-complexity account gives the FTIP hypothesis [dang2026selecting, Sections 5.2 and 6-7; Tables 4-5, 10]. Truncation can increase temporal-supervision bias by removing later decisions, while a longer continuation increases the policy complexity and finite-sample burden. The useful horizon is therefore conditional on the task law, teacher policy, model capacity, verifier, and retained state.
Selective refinement makes the data intervention explicit [dang2026selecting, Sections 6-7; Tables 4-5, 10]. A warm-start model is trained on a shorter horizon, continuation segments are scored by teacher-forced likelihood, and a fixed fraction is retained for longer-horizon refinement. The score measures compatibility with the warm-start policy, not intrinsic truth. High-likelihood selection can improve repeatability; the FTIP protocol tests whether low-likelihood or random selection preserves breadth, rare strategies, and recovery behavior.
A run is premature when it terminates before the declared evidence or recovery condition, productive when it continues through bounded evidence gathering, verification, and recovery, and over-persistent when additional work repeats or explores after task-relevant value has saturated. Record coverage loss separately: a selector can improve repeatability while deleting hard tasks or unusual recovery paths. These terms describe observable behavior; they are not claims about an agent's memory or inner objective.
Definition 4.2.1.2. Trace record and state boundary [ftip-00P5]AGENTDRAFTED
Definition 4.2.1.2. Trace record and state boundary [ftip-00P5]AGENTDRAFTED
A long-horizon training trace should preserve the behavior that a later agent must learn: its decisions, evidence, verification, recovery, and the state boundary visible to the continuation. Fix event domains \(\mathcal O_{\rm evt}\), \(\mathcal A_{\rm evt}\), \(\mathcal Y_{\rm evt}\), \(\mathcal E_{\rm evt}\), and \(\mathcal V_{\rm evt}\), together with a termination domain \(\mathcal T_{\rm evt}\) and a boundary domain \(\mathcal S_{\rm boundary}\). The horizon comparison and selective-refinement intervention in [dang2026selecting, Sections 3-7] motivate this adaptation; the typed record below is an FTIP protocol proposal.
For \(H\in \mathbb N\), a trace record is
\[ T=(o_{0:H},a_{0:H},y_{0:H},e_{0:H},v_{0:H},\tau ,\sigma ,\kappa ) \in \mathcal O_{\rm evt}^{H+1}\times \mathcal A_{\rm evt}^{H+1} \times \mathcal Y_{\rm evt}^{H+1}\times \mathcal E_{\rm evt}^{H+1} \times \mathcal V_{\rm evt}^{H+1}\times \mathcal T_{\rm evt} \times \mathcal S_{\rm boundary}\times \mathbb N. \]The components \(o\), \(a\), and \(y\) are observation, action, and outcome events; \(e\) records evidence or an environment-state reference; \(v\) records verification or recovery; \(\tau \) records termination; \(\sigma \) records the state boundary; and \(\kappa \) is token length. The horizon \(H\) and token length \(\kappa \) are separate coordinates. A task may use a declared subtype of each event domain, but it must preserve the coordinate meaning.
The record is a training datum only together with its declared boundary \(\sigma \): a continuation may access exactly the state coordinates allowed by that boundary. The record therefore supports a later selector or run kernel without treating token count as a proxy for the events that make continuation useful.
This is a protocol definition rather than a formal theorem; the event domains and transition semantics must be instantiated by the experiment that uses the record.
Definition 4.2.1.3. Persistence classes of a retained trace [ftip-00P6]AGENTDRAFTED
Definition 4.2.1.3. Persistence classes of a retained trace [ftip-00P6]AGENTDRAFTED
Fix a trace record \(T\) from Definition 4.2.1.2 and a declared receipt interface with event indicators \(e_{\rm term}(t)\), \(e_{\rm ev}(t)\), \(e_{\rm pass}(t)\), \(e_{\rm fail}(t)\), \(e_{\rm rec}(t)\) and a productive-novelty indicator \(n_{\rm prod}(t)\) for \(0\leq t\leq H\). Let \(u(t)\) be the declared task-value score and \(u^{\rm sat}\) its saturation threshold. The source's reported horizon tradeoff and selective refinement [dang2026selecting, Sections 5.2 and 6-7; Tables 4-5, 10] motivate these observable classes, which are an FTIP proposal. Write
\[ \tau _{\rm end}:=\inf \{t:e_{\rm term}(t)=1\},\quad \tau _{\rm ev}:=\inf \{t:e_{\rm ev}(t)=1\},\quad \tau _{\rm pass}:=\inf \{t:e_{\rm pass}(t)=1\}, \]\[ \tau _{\rm fail}:=\inf \{t:e_{\rm fail}(t)=1\},\quad \tau _{\rm rec}:=\inf \{t:e_{\rm rec}(t)=1\},\quad \tau _{\rm sat}:=\inf \{t:u(t)\geq u^{\rm sat}\}, \]with \(\inf \varnothing :=+\infty \). The receipt declares all indicators and the score as functions of the same run, so the following classes are replayable predicates rather than impressions about an agent's inner state.
\[ \operatorname {Prem}(T):=\mathbf 1[\tau _{\rm end}<\tau _{\rm ev}\lor (\tau _{\rm fail}<\tau _{\rm end}\land \tau _{\rm rec}\geq \tau _{\rm end})], \]\[ \operatorname {Prod}(T):=\mathbf 1[\tau _{\rm ev}<\tau _{\rm end}\land \tau _{\rm pass}<\tau _{\rm end}\land (\tau _{\rm fail}\geq \tau _{\rm end}\lor \tau _{\rm fail}<\tau _{\rm rec}<\tau _{\rm end})], \]\[ \operatorname {Over}(T):=\mathbf 1[\tau _{\rm sat}<\tau _{\rm end}\land \sum _{t=\tau _{\rm sat}}^{\tau _{\rm end}-1}n_{\rm prod}(t)=0]. \]A productive trace reaches evidence and a final verifier pass, and any failure before termination is followed by recovery. An over-persistent trace continues after saturation without another declared productive event. The experiment may refine \(n_{\rm prod}\) for a task family, but it must declare that predicate before comparing selectors.
Example 4.2.1.4. A retained build-repair trace [ftip-00P7]AGENTDRAFTED
Example 4.2.1.4. A retained build-repair trace [ftip-00P7]AGENTDRAFTED
The horizon and selective-refinement observations in [dang2026selecting, Sections 3-7] motivate the following finite classification. Consider a run whose task is to repair a failing build. The retained record contains the failing observation, the source edit, a test execution, and a final verifier pass. With the event interface of Definition 4.2.1.3, the test and verification steps contribute to \(e_{\rm ev}\), \(e_{\rm pass}\), and \(n_{\rm prod}\), so the record can satisfy \(\operatorname {Prod}(T)\).
If the test event is removed from the retained record, the same token budget can fail the productive predicate because the evidence chain is incomplete. If identical shell retries continue after \(\tau _{\rm sat}\) with no new productive event, \(\operatorname {Over}(T)\) can hold. This is a finite classification example; it does not claim that every short trace is better or that a model has an inner persistence objective.
4.2.2. Fixed-budget trace-selection protocol [ftip-00P3]AGENTDRAFTED
4.2.2. Fixed-budget trace-selection protocol [ftip-00P3]AGENTDRAFTED
The trace-selection intervention is a finite evaluation proposal. It compares horizon and selector choices at a declared retained budget while keeping the model, teacher, scaffold, task split, verifier, randomization law, and cost coordinates visible. The selective-refinement study supplies the comparison pattern; the typed interface, receipts, and estimators below are FTIP adaptations rather than source results [dang2026selecting, Sections 6-7; Tables 4-5, 10].
The route separates the experiment interface (Definition 4.2.2.1), its receipt-derived quantities (Definition 4.2.2.2), and a finite paired calculation (Example 4.2.2.3). No result is claimed until an implementation supplies the declared receipts.
Definition 4.2.2.1. Finite trace-selection experiment [ftip-00P8]AGENTDRAFTED
Definition 4.2.2.1. Finite trace-selection experiment [ftip-00P8]AGENTDRAFTED
The selective-refinement study compares fixed-horizon data interventions under a declared training and evaluation boundary [dang2026selecting, Sections 6-7; Tables 4-5, 10]. A trace-selection experiment is the following finite typed record.
Fix the P0 lifecycle arm set \(\mathcal A\), its boundary map \(r:\mathcal A\to \mathcal J\), mask map \(M:\mathcal A\to \mathcal P(\{s,h,w\})\), and endowment \(E_0\) from § 4.1 and § 4. Choose finite nonempty label sets
\[ \mathfrak H\subset \mathbb N,\qquad \mathfrak L,\qquad \mathfrak B\subset \mathbb N_{>0},\qquad \mathfrak D,\qquad \mathfrak R. \]A split map returns a triple
\[ \operatorname {split}:\mathfrak D\longrightarrow \{(Q_{\rm sel},Q_{\rm hold},Q_{\rm xb})\mid Q_{\rm sel},Q_{\rm hold},Q_{\rm xb}\subseteq \mathcal Q\text { are finite}\}, \]whose three outputs are pairwise disjoint and satisfy \(|Q_{\rm sel}|>0\), \(|Q_{\rm hold}|>0\); \(Q_{\rm xb}\) may be empty only when the experiment records that no cross-benchmark comparison is made. A randomization map \(\lambda _{\rm pair}:\mathfrak R\to \operatorname {Dist}(\mathcal G\times \mathcal G)\) supplies a joint source law for each paired comparison.
The experiment declares a finite, nonempty arm set \(\mathfrak A\subseteq \mathcal A\times \mathfrak H\times \mathfrak L\times \mathfrak B\times \mathfrak D\times \mathfrak R\). For each \(a\in \mathfrak A\), write its projections as
\[ (a_0(a),H_a,\ell _a,B_a,D_a,\eta _a),\qquad r_a:=r(a_0(a)),\quad M_a:=M(a_0(a)),\quad \mathcal R_a:=\lambda _{\rm pair}(\eta _a). \]The arm record additionally supplies one model, teacher, scaffold, verifier, task law, inference protocol, and componentwise budget. These objects are maps of \(a\), not implicit labels; paired arms must agree on every object except the factor named by their comparison. The split attached to \(D_a\) is written \((Q_{\rm sel,a},Q_{\rm hold,a},Q_{\rm xb,a})\); it also supplies a nonempty finite strategy-label set \(\mathfrak S_a\) and a receipt space \(\mathcal R_a^{\rm rec}\) containing a typed held-out outcome \(Y_a\in \mathcal Y_a\cup \{\bot \}\), a declared scalarization \(g_a:\mathcal Y_a\to \mathbb R\), and an admission field. For every paired comparison \((a,a')\), the record additionally declares the finite pairing space \(\mathcal P_{a,a'}:=(Q_{\rm hold,a}\cap Q_{\rm hold,a'}) \times \mathfrak S_a\times \mathfrak S_{a'}\) and a law \(\Lambda _{a,a'}\) on \(\mathcal G\times \mathcal G\times \mathcal P_{a,a'}\). The shared task coordinate in this law is the pairing key; the two strategy coordinates may differ.
For each arm, let \(\mathcal X^{\rm sel}_a\) be the finite candidate-pool space with \(1\leq B_a\leq |\mathcal X^{\rm sel}_a|\), and let \(\mathcal F^{\rm sel}_a\) be the sigma-field generated by the selection-time prefix, teacher-forced score, data-only trace metadata, and \(Q_{\rm sel,a}\). The metadata map excludes held-out outcomes, verifier outcomes, and post-selection continuation events. The selector is a measurable kernel with respect to this sigma-field
\[ \mathsf S_{a,\ell _a}:\mathcal X^{\rm sel}_a \longrightarrow \operatorname {Dist}\bigl (\{I\subseteq \mathcal X^{\rm sel}_a: |I|=B_a\}\bigr ). \]It therefore returns a retained index set of the declared size without access to held-out outcomes. Write \(\mathcal I_a:=\{I\subseteq \mathcal X^{\rm sel}_a:|I|=B_a\}\). A run kernel
\[ \mathsf K^{\rm run}_{a,\ell _a}: \mathcal X^{\rm sel}_a\times \mathcal I_a\times \mathcal G \times \mathcal Q\times \mathfrak S_a \longrightarrow \operatorname {Dist}(\mathcal R_a^{\rm rec}) \]maps a candidate pool, its retained index set, one component of the paired source draw, a task, and its arm-specific strategy coordinate to a receipt with an event sequence, task and strategy labels, final verifier outcome, typed held-out outcome, admission field, state and artifact hashes, and the charged token, tool, storage, restart, discarded trace, and verification costs, with exactly \(H_a+1\) event slots and a timeout receipt at the final slot when needed. For a paired comparison, \(\Lambda _{a,a'}\) supplies a common held-out task and the two strategy coordinates, while \(\mathcal R_a\) supplies the two source components before the kernels are applied. Thus an arm defines maps and kernels that use the selector output to produce replayable receipts; it does not merely list factors whose later meaning is left implicit.
The reset transition is \(\mathsf {Reset}_{r_a,M_a}\) from § 4.1. Horizon, selector, budget, split, and randomization are therefore attached to a concrete P0 state boundary and a concrete run kernel. This is an empirical protocol definition, not a theorem or a claim that any selector improves behavior.
Definition 4.2.2.2. Receipt metrics and paired contrasts [ftip-00P9]AGENTDRAFTED
Definition 4.2.2.2. Receipt metrics and paired contrasts [ftip-00P9]AGENTDRAFTED
The source compares retained-horizon choices under declared task and evaluation boundaries [dang2026selecting, Sections 6-7; Tables 4-5, 10]. Fix an arm \(a\in \mathfrak A\) from Definition 4.2.2.1 and a positive run count \(N_a\). Each receipt \(R_{a,i}\) exposes a finite event sequence \((e^{\rm term},e^{\rm ev},e^{\rm pass},e^{\rm fail},e^{\rm rec}, n^{\rm prod})_{t=0}^{H_a}\), a task label \(q_{a,i}\), a strategy label \(s_{a,i}\), a measurable task-value score \(u_{a,i}(t)\), a declared saturation threshold \(u_a^{\rm sat}\), and a typed held-out outcome \(Y_{a,i}\in \mathcal Y_a\cup \{\bot \}\), final verifier outcome \(v_{a,i}\), and complete-admission indicator \(A_{a,i}\). Define \(A_{a,i}:=\mathbf 1[q_{a,i}\in Q_{\rm hold,a}\land v_{a,i}=1 \land Y_{a,i}\in \mathcal Y_a]\); when \(A_{a,i}=0\), set \(Y_{a,i}:=\bot \). The receipt contract emits a terminal event by \(H_a\); an execution that would not terminate naturally receives a timeout terminal event at \(H_a\) and \(A_{a,i}=0\). Put \(\overline {\mathbb N}:=\mathbb N\cup \{+\infty \}\) and \(\inf \varnothing :=+\infty \).
\[ \tau ^{\rm end}_{a,i}:=\inf \{t:e^{\rm term}_{a,i}(t)=1\},\quad \tau ^{\rm ev}_{a,i}:=\inf \{t:e^{\rm ev}_{a,i}(t)=1\},\quad \tau ^{\rm pass}_{a,i}:=\inf \{t:e^{\rm pass}_{a,i}(t)=1\}, \]\[ \tau ^{\rm fail}_{a,i}:=\inf \{t:e^{\rm fail}_{a,i}(t)=1\},\quad \tau ^{\rm rec}_{a,i}:=\inf \{t:e^{\rm rec}_{a,i}(t)=1\},\quad \tau ^{\rm sat}_{a,i}:=\inf \{t:u_{a,i}(t)\geq u_a^{\rm sat}\}. \]Define the receipt predicates
\[ \begin {aligned} I^{\rm pre}_{a,i}&:=\mathbf 1[\tau ^{\rm end}_{a,i}<\tau ^{\rm ev}_{a,i}],\\ I^{\rm rec}_{a,i}&:=\mathbf 1[\tau ^{\rm fail}_{a,i}<\tau ^{\rm rec}_{a,i}<\tau ^{\rm end}_{a,i}],\\ I^{\rm prod}_{a,i}&:=\mathbf 1[\tau ^{\rm ev}_{a,i}<\tau ^{\rm end}_{a,i} \land \tau ^{\rm pass}_{a,i}<\tau ^{\rm end}_{a,i} \land (\tau ^{\rm fail}_{a,i}\geq \tau ^{\rm end}_{a,i} \lor I^{\rm rec}_{a,i}=1)],\\ I^{\rm over}_{a,i}&:=\mathbf 1[\tau ^{\rm sat}_{a,i}<\tau ^{\rm end}_{a,i} \land \sum _{t=\tau ^{\rm sat}_{a,i}}^{\tau ^{\rm end}_{a,i}-1} n^{\rm prod}_{a,i}(t)=0]. \end {aligned} \]Here \(n^{\rm prod}_{a,i}(t)\) is a declared productive-novelty indicator in the receipt, and \(I^{\rm rec}\) is zero when no failure precedes recovery. The five run rates are functions of the receipts, with the declared denominator \(N_a\):
\[ (\widehat p_a^{\rm pre},\widehat p_a^{\rm prod},\widehat p_a^{\rm over}, \widehat p_a^{\rm rec},\widehat p_a^{\rm pass}) :=\frac 1{N_a}\sum _{i=1}^{N_a} (I^{\rm pre}_{a,i},I^{\rm prod}_{a,i},I^{\rm over}_{a,i}, I^{\rm rec}_{a,i},\mathbf 1[\tau ^{\rm pass}_{a,i}<\tau ^{\rm end}_{a,i}]). \]For the finite held-out set, task and strategy coverage are
\[ \widehat C^{\rm task}_a:= \frac {|\{q\in Q_{\rm hold,a}:\exists i,\ q_{a,i}=q,\ A_{a,i}=1\}|} {|Q_{\rm hold,a}|},\qquad \widehat C^{\rm strat}_a:= \frac {|\{s\in \mathfrak S_a:\exists i,\ s_{a,i}=s,\ A_{a,i}=1\}|} {|\mathfrak S_a|}, \]where \(\mathfrak S_a\) is a declared nonempty strategy-label set. Every receipt reports both positive denominators and the admission rule.
For two paired arms \(a\) and \(a'\) that differ in one declared factor, let \(N:=\min (N_a,N_{a'})\). Define the common admitted index set \(J_{a,a'}:=\{i\leq N:A_{a,i}=A_{a',i}=1\}\) and \(N_{\rm pair}:=|J_{a,a'}|\). For \(i\in J_{a,a'}\), let \(Y_{a,i}\) and \(Y_{a',i}\) be their admitted held-out outcomes under the shared pairing law \(\Lambda _{a,a'}\), so \(q_{a,i}=q_{a',i}\). Compare their declared scalarizations \(g_a(Y_{a,i})\) and \(g_{a'}(Y_{a',i})\). When \(N_{\rm pair}\geq 2\), the primary finite contrast and its paired sample variance are
\[ \widehat \Delta _{a,a'}:= \frac 1{N_{\rm pair}}\sum _{i\in J_{a,a'}} \bigl (g_a(Y_{a,i})-g_{a'}(Y_{a',i})\bigr ),\qquad \widehat V_{a,a'}:= \frac 1{N_{\rm pair}-1}\sum _{i\in J_{a,a'}} \bigl ((g_a(Y_{a,i})-g_{a'}(Y_{a',i}))-\widehat \Delta _{a,a'}\bigr )^2. \]When \(N_{\rm pair}=1\), report the single paired contrast but set \(\widehat V_{a,a'}:=\bot \); when \(N_{\rm pair}=0\), the paired contrast is undefined and the missingness is reported. These are finite estimators under the declared arm, split, admission rule, and coupling; they are not a universal selector law.
Example 4.2.2.3. A paired trace-selection calculation [ftip-00PA]AGENTDRAFTED
Example 4.2.2.3. A paired trace-selection calculation [ftip-00PA]AGENTDRAFTED
The selective-refinement comparison motivates contrasting repeatability and coverage under a fixed retained budget [dang2026selecting, Sections 6-7; Tables 4-5, 10]. Consider two arms from Definition 4.2.2.1 with the same P0 boundary, model, task split, verifier, budget, and paired assignment law. They differ only in the selector: \(a\) retains the highest teacher-forced scores and \(a'\) retains a coverage-stratified subset. Both have \(Q_{\rm hold}=\{q_1,q_2\}\) and \(\mathfrak S=\{s_1,s_2\}\). The paired assignment law gives the same held-out task at indices 1 and 2; arm \(a'\) has one additional admitted coverage run at index 3. Take \(g_a=g_{a'}=\operatorname {id}_{\{0,1\}}\). The receipts are
\[ \begin {array}{c|cc|ccc} &q_{a,i}&s_{a,i}&A_{a,i}&I^{\rm prod}_{a,i}&Y_{a,i}\\\hline i=1&q_1&s_1&1&1&1\\ i=2&q_1&s_1&1&1&0 \end {array} \qquad \begin {array}{c|cc|ccc} &q_{a',i}&s_{a',i}&A_{a',i}&I^{\rm prod}_{a',i}&Y_{a',i}\\\hline i=1&q_1&s_1&1&1&1\\ i=2&q_1&s_1&1&1&1\\ i=3&q_2&s_2&1&1&1 \end {array} \]The first two rows are the common paired indices, so \(N_a=2\), \(N_{a'}=3\), and \(N_{\rm pair}=2\). Both arms have \(\widehat p^{\rm prod}=1\); the third row is included in arm \(a'\)'s coverage and run-rate denominators but not in the paired contrast. Thus \(\widehat C^{\rm task}_a=\widehat C^{\rm strat}_a=\tfrac 12\) and \(\widehat C^{\rm task}_{a'}=\widehat C^{\rm strat}_{a'}=1\), while \(\widehat \Delta _{a,a'}=-\tfrac 12\). The calculation shows why a repeatability rate alone cannot identify coverage: the two selectors have the same productive rate but different admitted task and strategy support. This is a finite FTIP construction using the typed receipt and pairing definitions, not a source result.
With the trace schema and the fixed-budget protocol now in scope, the FTIP boundary is operational: an admitted trace must preserve the declared decision, evidence, verification, and recovery events, and every selector comparison must report the finite run rates, held-out task and strategy coverage, and charged selection/storage/restart costs defined in § 4.2.2. A result may claim a selection benefit only when its immutable arm, split, seed, and randomization receipt supports that comparison.