Example. The orthogonal gauge of an attention head [ftip-00BX]
Example. The orthogonal gauge of an attention head [ftip-00BX]
For the row-vector attention weights of Definition [ftip-000P], let \(W^Q,W^K\in \mathbb R^{d\times d_h}\) and \(Q_h=XW^Q\), \(K_h=XW^K\). Attention logits depend on these weights through
\[ Q_hK_h^{\mathsf T}=XW^Q(W^K)^{\mathsf T}X^{\mathsf T}. \]For \(A\in \mathrm O(d_h)\), the right action \((W^Q,W^K)\mapsto (W^QA,W^KA)\) preserves the middle product.
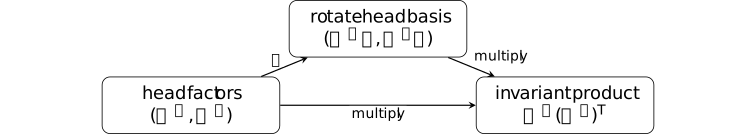
Section 6 of The loss does not see the basis, but Adam does[singh2026lossbasis] uses column-vector weights and the invariant \(W_Q^{\mathsf T}W_K\). Transposition gives the row-vector invariant \(W^Q(W^K)^{\mathsf T}\), with the action on the right as displayed.