Reinforcement-learning foundations [ftip-002W]
✍️sourceAGENTDRAFTED
Reinforcement-learning foundations [ftip-002W]
✍️sourceAGENTDRAFTED
Reinforcement learning updates a policy from rewards attached to sampled behavior. Before considering a particular alignment method, this section fixes the response-level episode, return, value, advantage, policy roles, and likelihood ratios used by policy-gradient objectives.
Notation 1. Reward, return, policy roles, value, advantage, and likelihood ratios [ftip-002X]AGENTDRAFTED
Notation 1. Reward, return, policy roles, value, advantage, and likelihood ratios [ftip-002X]AGENTDRAFTED
The ratio and policy-objective formulas in this section specialize the measurable policy interface of Definition [ftip-0023] to a declared finite or countable discrete action space. Thus \(\pi (a\mid h)\) denotes probability mass, not an unspecified density. Whenever \(\log \pi _\theta (A_t\mid H_t)\) is displayed, its sampled mass is assumed positive.
For decision times \(t=0,\ldots ,N-1\), write \(\mathsf H_t:=H_t\) for the public history defined in Definition [ftip-0021], \(A_t\) for its action, and \(R_{t+1}\in \mathbb R\) for the next reward. Let \(\gamma \in [0,1]\) be the discount factor and \(G_t\) the return from time \(t\).
Write \(\pi _b\) for the behavior policy that produced a stored action, \(\pi _\theta \) for the current trainable policy, and \(\pi _{\mathrm {ref}}\) for a fixed reference policy. Their value, action-value, and advantage functions are denoted \(V^\pi \), \(Q^\pi \), and \(A^\pi \); an estimated advantage is \(\widehat A_t\). The current-to-behavior likelihood ratio is denoted \(\rho _t(\theta )\).
In a response-level episode, \(\pi _\theta (y\mid x)\) abbreviates the completed-continuation probability \(P_\theta (y\mid s_{\mathrm {pr}}(x))\) of the response-task interface, using the declared prompt serializer; the same convention applies to \(\pi _b\) and \(\pi _{\mathrm {ref}}\). In an interactive episode these symbols instead denote the action laws on public histories defined in Definition [ftip-0023].
Definition 2. Response-level episode [ouyang2022training, Section 3.5] [ftip-002Y]AGENTDRAFTED
Definition 2. Response-level episode [ouyang2022training, Section 3.5] [ftip-002Y]AGENTDRAFTED
In the response-level specialization used for language-model RLHF, a prompt \(x\) is the initial context, a complete response \(y\sim \pi _\theta (\mathord \cdot \mid x)\) is the sampled action, and a scalar score supplies the terminal reward. The episode terminates after that response.
This contextual-bandit view is sufficient for sequence-level reward-model training. Token generation may still be exposed as multiple policy decisions when an optimizer assigns token-level likelihood ratios or advantages. A later agentic setting also permits environment observations and tool actions between model responses.
Definition 3. Scalar reward [sutton2018reinforcement, Section 3.2] [ftip-002Z]AGENTDRAFTED
Definition 3. Scalar reward [sutton2018reinforcement, Section 3.2] [ftip-002Z]AGENTDRAFTED
A scalar reward \(R_{t+1}\in \mathbb R\) is the numerical signal received after action \(A_t\) and before the next decision. Its probabilistic law may depend on the current history, action, and environment transition.
Reward specifies the training objective of the reinforcement-learning problem. It need not equal an independent evaluator's utility, and a terminal reward need not identify which earlier action caused the outcome.
Definition 4. Return [sutton2018reinforcement, Section 3.3] [ftip-0030]AGENTDRAFTED
Definition 4. Return [sutton2018reinforcement, Section 3.3] [ftip-0030]AGENTDRAFTED
For an episode ending at time \(N\), the return from decision time \(t\) is
\[ G_t=\sum _{k=t}^{N-1}\gamma ^{k-t}R_{k+1}. \]When all intermediate rewards vanish, every return is determined by the terminal reward, up to discounting. Return is a random variable under the policy and environment law; its expectation defines value.
Definition 5. Value function [sutton2018reinforcement, Section 3.5] [ftip-0031]AGENTDRAFTED
Definition 5. Value function [sutton2018reinforcement, Section 3.5] [ftip-0031]AGENTDRAFTED
For a policy \(\pi \), the value function and action-value function are
\[ V^\pi (h)=\mathbb E_\pi [G_t\mid \mathsf H_t=h], \qquad Q^\pi (h,a)=\mathbb E_\pi [G_t\mid \mathsf H_t=h,A_t=a], \]whenever the conditional expectations exist. Both quantities depend on the reward, transition law, horizon, discount, and the policy followed after the conditioned decision.
Definition 6. Advantage function [schulman2016gae, Section 2] [ftip-0032]AGENTDRAFTED
Definition 6. Advantage function [schulman2016gae, Section 2] [ftip-0032]AGENTDRAFTED
For a policy \(\pi \), its advantage function is
\[ A^\pi (h,a)=Q^\pi (h,a)-V^\pi (h). \]The advantage compares an action with the policy's average continuation value at the same information state. Policy-gradient implementations replace it by an estimator \(\widehat A_t\); the estimator and the mathematical advantage are not interchangeable without assumptions on bias and variance.
Remark 7. Baselines and estimated credit [schulman2016gae, Sections 2--3] [ftip-0033]AGENTDRAFTED
Remark 7. Baselines and estimated credit [schulman2016gae, Sections 2--3] [ftip-0033]AGENTDRAFTED
Subtracting a baseline that does not depend on the sampled action can reduce the variance of a policy-gradient estimator without changing its expected gradient under the source conditions. A learned value function, a group mean, and a leave-one-out mean are different baselines and have different finite-data dependencies.
An estimated advantage may use sampled returns, bootstrapped values, or a mixture of both. Its error enters the update even when the likelihood-ratio calculation is exact.
Definition 8. Behavior, current, and reference policies [schulman2017proximal, Sections 2--3] [ftip-0034]AGENTDRAFTED
Definition 8. Behavior, current, and reference policies [schulman2017proximal, Sections 2--3] [ftip-0034]AGENTDRAFTED
The behavior policy \(\pi _b\) is the policy that generated a sampled action. The current policy \(\pi _\theta \) is the policy whose parameters are being optimized. Proximal policy optimization (PPO) collects a batch under an old policy and then compares candidate current policies with that data.
A reference policy \(\pi _{\mathrm {ref}}\) is instead held fixed to define a regularizer or preference objective; see [rafailov2023direct, Section 3, equation (3)]. It need not equal the behavior policy that generated a later rollout.
Definition 9. Likelihood ratio [schulman2017proximal, Section 2, equation (3)] [ftip-0035]AGENTDRAFTED
Definition 9. Likelihood ratio [schulman2017proximal, Section 2, equation (3)] [ftip-0035]AGENTDRAFTED
For an action \(A_t\) sampled from \(\pi _b\) at information state \(\mathsf H_t\), the current-to-behavior likelihood ratio is
\[ \rho _t(\theta ) =\frac {\pi _\theta (A_t\mid \mathsf H_t)}{\pi _b(A_t\mid \mathsf H_t)}. \]The ratio is defined on sampled actions for which \(\pi _b(A_t\mid \mathsf H_t)>0\). A bounded or clipped sampled ratio does not by itself control policy probabilities at unvisited histories.
Convention 10. Empirical sample average [ftip-006Z]AGENTDRAFTED
Convention 10. Empirical sample average [ftip-006Z]AGENTDRAFTED
For a nonempty finite index set \(I\) and real values \((Z_i)_{i\in I}\in \mathbb R^I\), write \[ \widehat {\mathbb E}_{i\in I}[Z_i] =\frac 1{|I|}\sum _{i\in I}Z_i. \] When the subscript is only \(t\), the index set is the declared collection of sampled decision times in the current batch.
PPO uses empirical expectation notation for its sampled surrogates; see Section 2, equations (1)--(2) of [schulman2017proximal]. The batch and its weighting must still be declared; the hat does not assert unbiasedness.
Definition 11. Policy-gradient surrogate [schulman2017proximal, Section 2, equations (1)--(2)] [ftip-0036]AGENTDRAFTED
Definition 11. Policy-gradient surrogate [schulman2017proximal, Section 2, equations (1)--(2)] [ftip-0036]AGENTDRAFTED
For samples collected under the declared behavior law and estimated advantages \(\widehat A_t\), the empirical policy-gradient surrogate is the following sample average:
\[ L^{\mathrm {PG}}(\theta ) =\widehat {\mathbb E}_t \left [\log \pi _\theta (A_t\mid \mathsf H_t)\,\widehat A_t\right ]. \]Its gradient is the familiar score-function estimator. The sampled states, actions, and advantage estimator are held fixed while differentiating this surrogate; changing the data-collection law defines a different estimator.
Example 12. Return and advantage on a three-step episode [ftip-0037]AGENTDRAFTED
Example 12. Return and advantage on a three-step episode [ftip-0037]AGENTDRAFTED
On a three-step episode, a discounted return and a baseline-relative advantage can be computed separately.
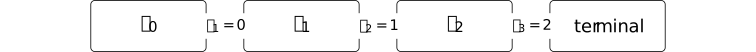
Take discount \(\gamma =1/2\). The return attached to the first action is \[ G_0=r_1+\gamma r_2+\gamma ^2 r_3 =0+\tfrac 12+\tfrac 14\cdot 2=1. \] If the declared baseline is \(V(s_0)=0.4\), then the corresponding advantage estimate is \(\widehat A_0=G_0-V(s_0)=0.6\).
The calculation instantiates the return and advantage in Definition 4 and Definition 6. It illustrates one baseline choice. Low variance and correct attribution of terminal reward to an internal decision require additional assumptions or evidence.
Remark 13. Delayed credit and estimator scope [ftip-0038]AGENTDRAFTED
Remark 13. Delayed credit and estimator scope [ftip-0038]AGENTDRAFTED
A terminal response score can be copied into returns for many token decisions, but that bookkeeping does not reveal which token caused the score.
Monte Carlo returns, learned values, generalized advantage estimation, and group-relative normalization make different bias, variance, and dependence choices. Any theorem about an update must name the estimator actually used, the behavior policy that supplied its samples, and the horizon over which its credit signal is propagated.