Example. The InstructGPT-style RLHF pipeline [ftip-003J]
Example. The InstructGPT-style RLHF pipeline [ftip-003J]
One prompt passes successively through supervised tuning, comparison-based reward modeling, and PPO in the InstructGPT-style RLHF pipeline.
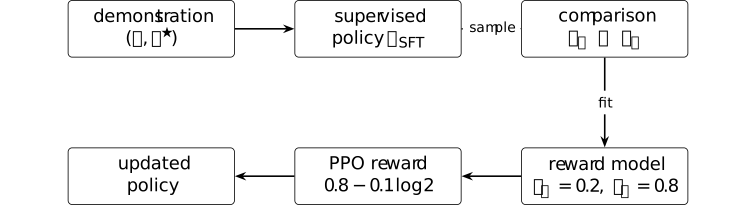
For the displayed illustrative prompt, suppose the comparison-trained reward model scores the preferred response by \(0.8\). If the candidate policy assigns it twice the probability assigned by the reference policy and the declared KL coefficient is \(\beta =0.1\), its shaped scalar is \[ 0.8-\beta \log \frac {\pi (y_B\mid x)} {\pi _{\rm ref}(y_B\mid x)} =0.8-0.1\log 2\approx 0.731. \]
The stage ordering is grounded in [ouyang2022training, Sections 3.1--3.5]; the numbers are a schematic calculation rather than reported InstructGPT hyperparameters. The diagram records the interface used in that pipeline. Other RLHF systems may order or replace the stages differently.