Finite KL-regularized alignment [ftip-008F]
✍️sourceAGENTDRAFTED
Finite KL-regularized alignment [ftip-008F]
✍️sourceAGENTDRAFTED
This subsection studies an exact, finite optimization model. A reference law is exponentially tilted by a declared scalar reward. In this setting, reward gain admits two exact descriptions: a Jeffreys-divergence identity and a covariance under the reference law.
The statements do not model approximate optimization, neural training cost, reward validity, or independent capability evaluation.
Remark 1. Exact optimization on a finite response set [ftip-008G]AGENTDRAFTED
Remark 1. Exact optimization on a finite response set [ftip-008G]AGENTDRAFTED
Theorems 1 and 2 of the v1 preprint [paes2026theoretical] concern an exactly optimal KL-regularized policy and a fixed query. On a finite response set, their expectations and normalizers are ordinary finite sums.
These exact identities do not establish a comparison among best-of-\(N\), PPO, and GRPO, or a general guarantee for proxy rewards and reward ensembles. Those questions require assumptions beyond exact optimization of one reward.
Notation 2. Translating the alignment source notation [ftip-008H]AGENTDRAFTED
Notation 2. Translating the alignment source notation [ftip-008H]AGENTDRAFTED
The source writes \(\lambda >0\) for the KL penalty. Here we write \(\beta >0\), matching the DPO notation in Notation [ftip-003M]--Definition [ftip-003O]. This avoids collision with the generalized-advantage parameter in Definition [ftip-003E] and the protocol law in Definition [ftip-007Q].
The source's gain \(\Delta (r,r')\) is written \(G_p(r;s)\): \(r\) is the reward used to tilt the reference law \(p\), while \(s\) is the reward used to evaluate the tilted law. This avoids collision with both the simplex notation \(\Delta (X)\) of Notation [ftip-000A] and the paired DPO margin of Notation [ftip-003M]. For a finite set \(\mathcal Y\), a law \(p\in \Delta (\mathcal Y)\), and functions \(f,g:\mathcal Y\to \mathbb R\), set
\[ \operatorname {Cov}_p(f,g) =\mathbb E_{y\sim p}[f(y)g(y)] -\mathbb E_{y\sim p}[f(y)]\, \mathbb E_{y\sim p}[g(y)]. \]
Definition 3. Finite KL-alignment instance [ftip-008I]AGENTDRAFTED
Definition 3. Finite KL-alignment instance [ftip-008I]AGENTDRAFTED
A finite KL-alignment instance consists of a nonempty finite response set \(\mathcal Y\), a reference law \(p\in \Delta (\mathcal Y)\), a penalty \(\beta >0\), and finite real functions \(r,s:\mathcal Y\to \mathbb R\). The reference support is
\[ S_p=\{y\in \mathcal Y:p(y)>0\}. \]A prompt is fixed and suppressed. The function \(r\) determines the alignment update; \(s\) measures its result. They may coincide, but they need not. Finiteness makes every exponential weight and expectation below finite.
These objects specialize the fixed-query setting in [paes2026theoretical, Section 2, equations (2.1)--(2.2)]; they are not a definition of alignment in general.
Definition 4. Exponential weight and partition function [ftip-008J]AGENTDRAFTED
Definition 4. Exponential weight and partition function [ftip-008J]AGENTDRAFTED
For a finite KL-alignment instance, define the exponential weight and partition function by
\[ a_r(y)=\exp \left (\frac {r(y)}{\beta }\right ), \qquad Z_r=\mathbb E_{y\sim p}[a_r(y)]. \]Every \(a_r(y)\) is finite and strictly positive. Since \(p\) is a probability law on a nonempty finite set, \(0<Z_r<\infty \).
This weight and normalizer are the fixed-query form of [paes2026theoretical, Equation (2.2)].
Definition 5. Aligned law in finite-source notation [ftip-008K]AGENTDRAFTED
Definition 5. Aligned law in finite-source notation [ftip-008K]AGENTDRAFTED
The aligned law induced by \(r\) is \(q_r\in \Delta (\mathcal Y)\) given by
\[ q_r(y)=\frac {p(y)a_r(y)}{Z_r}. \]Normalization follows from the definition of \(Z_r\). Moreover, \(q_r(y)>0\) exactly when \(p(y)>0\). This is the finite notation for the same exponential-tilt optimizer stated in Definition [ftip-003O]; support preservation was proved in Theorem [ftip-007C].
This formula is [paes2026theoretical, Equation (2.2)]. It assumes the exact optimizer, not an iterate returned by a particular training algorithm.
Definition 6. Cross-reward gain under an alignment reward [ftip-008L]AGENTDRAFTED
Definition 6. Cross-reward gain under an alignment reward [ftip-008L]AGENTDRAFTED
The cross-reward gain from aligning with \(r\) and evaluating with \(s\) is
\[ G_p(r;s) =\mathbb E_{y\sim q_r}[s(y)] -\mathbb E_{y\sim p}[s(y)]. \]The semicolon records two roles. Its left argument changes the response law; its right argument scores both laws. Thus \(G_p(r;s)\) is not an independent evaluation unless \(s\) has separately been declared to serve that role.
This is the finite notation for \(\Delta (r,r')\) in Theorem 2, equation (3.4), of Theoretical limits of language model alignment[paes2026theoretical].
Definition 7. Jeffreys divergence [ftip-008M]AGENTDRAFTED
Definition 7. Jeffreys divergence [ftip-008M]AGENTDRAFTED
For probability laws \(p\) and \(q\) for which both terms are finite, their Jeffreys divergence is
\[ J(p,q) =D_{\mathrm {KL}}(p\Vert q) +D_{\mathrm {KL}}(q\Vert p). \]The KL divergence and its argument order are defined in Definition [ftip-006X]. Unlike either directed term, \(J(p,q)=J(q,p)\). In the finite tilt of Definition 5, \(p\) and \(q_r\) have the same support, so both terms are finite.
Lemma 8. Log-density ratio of the exact tilt [ftip-008N]AGENTDRAFTED
Lemma 8. Log-density ratio of the exact tilt [ftip-008N]AGENTDRAFTED
For every \(y\in S_p\), the aligned law satisfies
\[ \log \frac {q_r(y)}{p(y)} =\frac {r(y)}{\beta }-\log Z_r. \]
Proof.
Proof.
On \(S_p\), both \(p(y)\) and \(q_r(y)\) are positive. Dividing the formula of Definition 5 by \(p(y)\) and taking logarithms gives the identity.
This is equation (B.1) followed by the logarithmic step in [paes2026theoretical, Appendix B.1, equations (B.1)--(B.2)].
Theorem 9. Exact reward gain equals scaled Jeffreys divergence [ftip-008O]AGENTDRAFTED
Theorem 9. Exact reward gain equals scaled Jeffreys divergence [ftip-008O]AGENTDRAFTED
For a finite KL-alignment instance,
\[ G_p(r;r)=\beta J(p,q_r). \]
Proof.
Proof.
Rearranging Lemma 8 gives \(r(y)=\beta \log (q_r(y)/p(y))+\beta \log Z_r\) on the common support. Taking expectation first under \(q_r\) and then under \(p\) yields
\[ \begin {aligned} \mathbb E_{q_r}[r] &=\beta D_{\mathrm {KL}}(q_r\Vert p)+\beta \log Z_r,\\ \mathbb E_p[r] &=-\beta D_{\mathrm {KL}}(p\Vert q_r)+\beta \log Z_r. \end {aligned} \]Subtracting cancels the common normalizer and gives the result.
This is the finite form of [paes2026theoretical, Theorem 1, equation (3.2), with proof in Appendix B.1].
Remark 10. What the Jeffreys identity does and does not identify [ftip-008P]AGENTDRAFTED
Remark 10. What the Jeffreys identity does and does not identify [ftip-008P]AGENTDRAFTED
The identity Theorem 9 is an equality inside one declared model. It says that exact gain in the optimizing reward equals a symmetric divergence from the reference law. It does not say that a larger divergence improves a different utility, nor that a training algorithm reaches the exact tilt.
The identity accounts for neither rollout and update work nor the cost of obtaining \(r\). Consequently it is not, by itself, a bound on the costed post-training potential of Definition [ftip-005M].
Theorem 11. Cross-reward gain is a base-law covariance [ftip-008Q]AGENTDRAFTED
Theorem 11. Cross-reward gain is a base-law covariance [ftip-008Q]AGENTDRAFTED
For a finite KL-alignment instance,
\[ G_p(r;s) =\operatorname {Cov}_p\left (s,\frac {a_r}{Z_r}\right ). \]
Proof.
Proof.
The aligned expectation can be written under the reference law as \(\mathbb E_{q_r}[s]=\mathbb E_p[s a_r/Z_r]\). Also \(\mathbb E_p[a_r/Z_r]=1\). Substituting these two identities into Definition 6 gives the covariance defined in Notation 2.
This is the finite form of Theorem 2, equation (3.4), in Theoretical limits of language model alignment[paes2026theoretical]. Its proof is in Appendix B.1, equations (B.5)--(B.7).
Remark 12. The covariance is predictive only for a declared reward [ftip-008R]AGENTDRAFTED
Remark 12. The covariance is predictive only for a declared reward [ftip-008R]AGENTDRAFTED
The identity Theorem 11 expresses exact tilted-law gain using expectations under \(p\). This makes the population quantity accessible from the reference law in principle. A finite-sample estimator still needs its own sampling law, moment assumptions, and error analysis.
The formula also remains indexed by both \(r\) and \(s\). It cannot turn a proxy reward into an independent utility. If \(s=r\), it measures improvement in the same quantity that defined the exact optimizer; if \(s\ne r\), its sign is determined by the displayed covariance.
Example 13. A two-response alignment identity [ftip-008S]AGENTDRAFTED
Example 13. A two-response alignment identity [ftip-008S]AGENTDRAFTED
Take \(\mathcal Y=\{a,b\}\), \(p=(1/2,1/2)\), \(\beta =1\), and \(r(a)=0\), \(r(b)=\log 3\). Exponential weighting changes the reference law as follows.
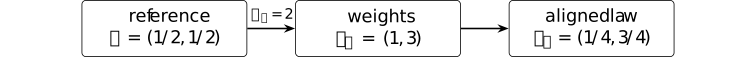
The reward gain is
\[ G_p(r;r) =\left (\frac 34-\frac 12\right )\log 3 =\frac 14\log 3. \]Direct calculation gives
\[ \begin {aligned} D_{\mathrm {KL}}(q_r\Vert p) &=\frac 14\log \frac 12+\frac 34\log \frac 32,\\ D_{\mathrm {KL}}(p\Vert q_r) &=\frac 12\log 2+\frac 12\log \frac 23, \end {aligned} \]whose sum is \(\frac 14\log 3\). Thus the example checks Theorem 9 exactly; it is not an empirical alignment result.
Corollary 14. Averaging the fixed-query identity over prompts [ftip-008T]AGENTDRAFTED
Corollary 14. Averaging the fixed-query identity over prompts [ftip-008T]AGENTDRAFTED
Let \(\mathcal X\) be finite with prompt law \(\mu \). For each \(x\in \mathcal X\), let \(p_x\), \(r_x\), and \(q_{r_x}\) be a finite KL-alignment instance with the same penalty \(\beta >0\). Then
\[ \sum _{x\in \mathcal X}\mu (x)G_{p_x}(r_x;r_x) =\beta \sum _{x\in \mathcal X}\mu (x)J(p_x,q_{r_x}). \]
Proof.
Proof.
Apply Theorem 9 at each prompt and take the finite \(\mu \)-weighted sum.
The source theorem is stated for each fixed query. This corollary performs only finite averaging; it does not introduce a shared neural parameterization across prompts.
Lemma 15. Additive reward shifts leave the aligned law unchanged [ftip-008U]AGENTDRAFTED
Lemma 15. Additive reward shifts leave the aligned law unchanged [ftip-008U]AGENTDRAFTED
For constants \(c,d\in \mathbb R\),
\[ q_{r+c}=q_r, \qquad G_p(r+c;s+d)=G_p(r;s). \]
Proof.
Proof.
The shifted weight is \(a_{r+c}=e^{c/\beta }a_r\), while its partition function is \(Z_{r+c}=e^{c/\beta }Z_r\); the common factor cancels in the aligned law. Adding \(d\) to the evaluation reward adds \(d\) to both expectations in the gain, so it also cancels.
This finite lemma records the same prompt-dependent additive non-identifiability that appears in the DPO reparameterization of Definition [ftip-003P].
Remark 16. A penalty coefficient is not a hard KL budget [ftip-008V]AGENTDRAFTED
Remark 16. A penalty coefficient is not a hard KL budget [ftip-008V]AGENTDRAFTED
For fixed \(\beta \), the exponential tilt solves the penalized problem
\[ \max _{q\in \Delta (\mathcal Y)} \left \{\mathbb E_q[r] -\beta D_{\mathrm {KL}}(q\Vert p)\right \} \]under the conventions of Definition 3. This is not the same specification as choosing a number \(\kappa \) and solving
\[ \max _q\mathbb E_q[r] \quad \text {subject to}\quad D_{\mathrm {KL}}(q\Vert p)\leq \kappa . \]A Lagrange multiplier can relate the two problems when the relevant duality and activity conditions hold. The coefficient \(\beta \) alone does not declare a hard budget, and the identities Theorem 9--Theorem 11 do not supply those conditions.
Remark 17. Fixed-query identities and their assumptions [ftip-008W]AGENTDRAFTED
Remark 17. Fixed-query identities and their assumptions [ftip-008W]AGENTDRAFTED
The source setup writes rewards as \(r(\mathbf x,\mathbf y)\), while the display of Theorem 1 reverses the two arguments in places. This subsection uses the setup order and then suppresses the fixed prompt. The source also moves between a dataset-level penalized objective and fixed-query identities. The finite-averaging result Corollary 14 makes that step explicit.
The identities specialize Theoretical limits of language model alignment[paes2026theoretical] to a finite response set. They require no extension to the full sequence space.
Finally, exact exponential tilting is a distributional optimizer. It does not account for rollout, gradient, optimizer, or systems cost, and it does not show that PPO, GRPO, DPO, or any frontier training run attains the displayed law. Applying the identities to a training run therefore requires a separate argument that its output law is the exact optimizer.