Example. Narrow and broad random-reward paths [ftip-00AQ]
Example. Narrow and broad random-reward paths [ftip-00AQ]
Section 5.3 and Appendix F of Demystifying Reinforcement Learning Post-Training of Language Models[clay2026demystifying] supply two OLMo paths; Figure 4 reports their outcomes. Both replace the usual verifiable reward with a random scalar drawn from \(\operatorname {Unif}[0,1]\), but their prompt configurations differ.
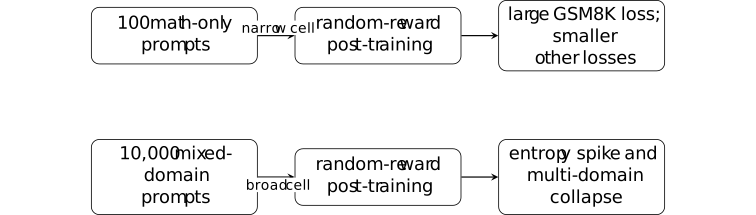
In the narrow SFT-start path, GSM8K accuracy falls from 86 to about 32 by step 400, while the reported MMLU and IFEval changes are much smaller. In the broad path, the source reports an entropy spike near step 400 together with collapse on GSM8K, MMLU, and IFEval. The diagram records that interpretation; it does not isolate prompt breadth from pool size, mixture, or repetition.