Example. One policy under two evaluation inference budgets [ftip-001U]
Example. One policy under two evaluation inference budgets [ftip-001U]
One fixed policy can receive different measured success rates when the evaluation horizon changes.
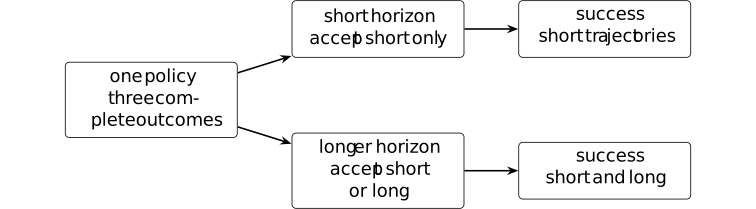
Partition complete trajectories into those that finish within the short horizon, those requiring additional tokens, and failures. The short protocol counts only the first class; the longer protocol may count the first two. Thus the measured score depends on the declared horizon even though the policy is unchanged.
Making an evaluation horizon explicit follows finite-horizon policy evaluation in [sutton2018reinforcement, Chapter 3]. Only truncation is varied here. Larger budgets need not help once decoding rules, tool costs, or selection errors are allowed to change with the budget.