Example. A two-record pretraining loss and minibatch estimate [ftip-001F]
Example. A two-record pretraining loss and minibatch estimate [ftip-001F]
Two equal-length records make a full empirical loss directly comparable with a minibatch estimate, while exposing the assumptions behind unbiasedness.
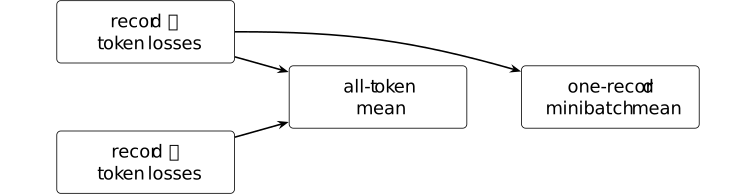
Let \(\ell _{ij}\) denote the token loss at position \(j\) of record \(i\). The full token-average loss is the mean of all \(\ell _{ij}\), while a one-record minibatch averages only the losses from its sampled record. Uniform sampling of equal-length records makes the latter unbiased for the former.
The preceding loss and estimator definitions apply to this equal-length record setup. Equal record lengths make the estimator unbiased here; unequal lengths, padding, dependence, and optimizer noise remain outside its scope.